Token单价更便宜,输出可能更贵?
大语言模型(LLM)的计费单位是 token:模型先把文本切成 token,再根据 token 数量计费和限制上下文。英文单词通常被切成 1~2 个 token,而中文往往一个汉字就要 1~3 个 token——所以同一段话,在不同模型上算出来的 token 数可能相差两三倍。例如 GPT-4o、Qwen、DeepSeek 使用的分词器就完全不同。
Token 切分(Qwen3.5-9B,共 94 个,显示前 40 个)
模型与词表
| 模型 | 厂商 | 国别 | 词表 | token |
|---|---|---|---|---|
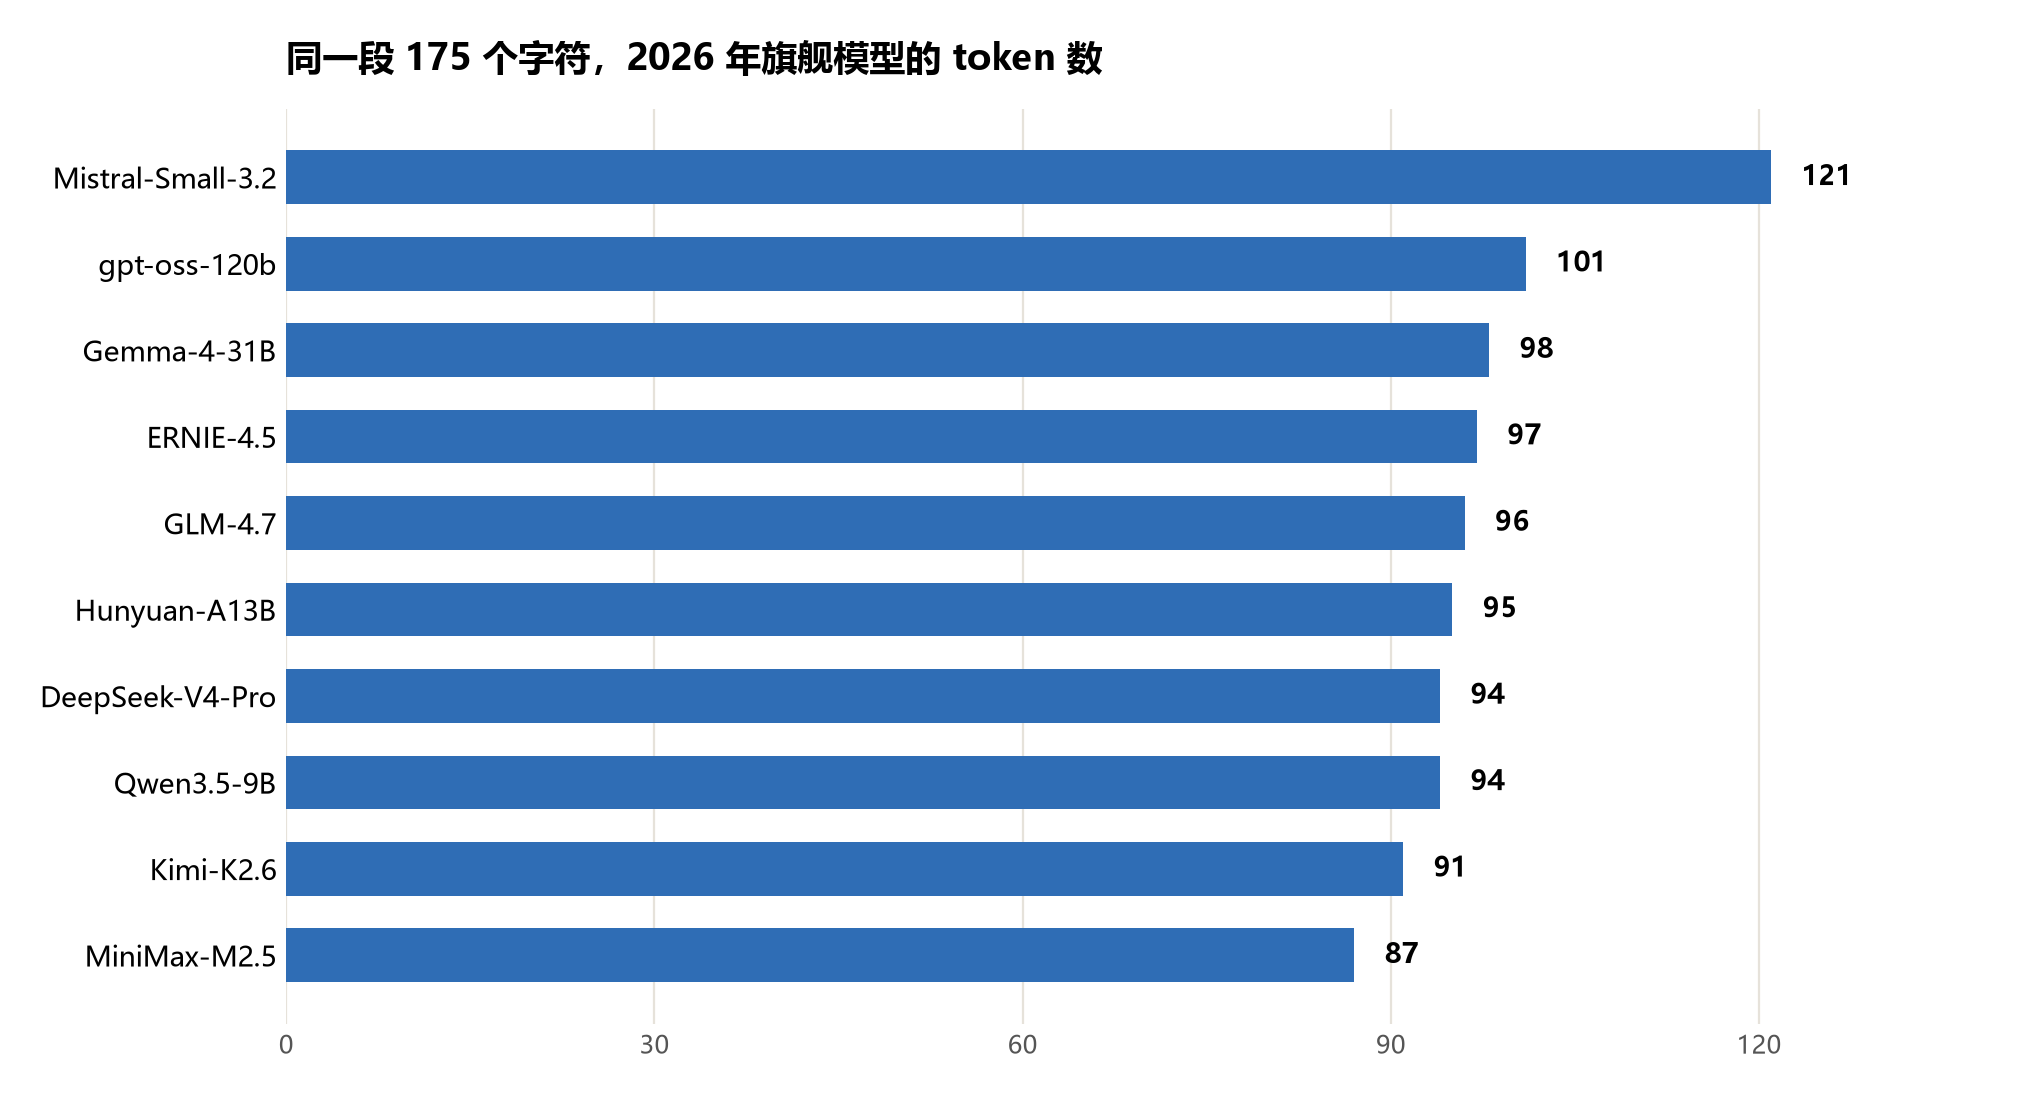
| MiniMax-M2.5 | MiniMax | 中国 | 200,054 | 87 |
| Kimi-K2.6 | 月之暗面 | 中国 | 163,840 | 91 |
| Qwen3.5-9B | 阿里 | 中国 | 248,070 | 94 |
| DeepSeek-V4-Pro | 深度求索 | 中国 | 129,280 | 94 |
| Hunyuan-A13B | 腾讯 | 中国 | 128,166 | 95 |
| GLM-4.7 | 智谱 | 中国 | 151,365 | 96 |
| ERNIE-4.5 | 百度 | 中国 | 100,309 | 97 |
| Gemma-4-31B | 美国 | 262,144 | 98 | |
| gpt-oss-120b | OpenAI | 美国 | 200,019 | 101 |
| Mistral-Small-3.2 | Mistral | 法国 | 131,072 | 121 |
tiktoken 编码(本次仅 gpt-oss 使用)
| 编码 | 对应模型 |
|---|---|
| o200k_harmony | gpt-oss-120b |
其余 9 款不经 tiktoken:7 款直接读 tokenizer.json;Kimi-K2.6 需要 trust_remote_code;Mistral-Small-3.2 用 mistral-common 的 Tekken。具体下载地址与加载代码见文末「数据来源与复现方法」。
单字 token 数
| 模型 | 大 | 语 | 言 | 模 | 型 | 中 | 文 | 英 |
|---|---|---|---|---|---|---|---|---|
| MiniMax-M2.5 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 |
| Kimi-K2.6 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 |
| Qwen3.5-9B | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 |
| DeepSeek-V4-Pro | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 |
| Hunyuan-A13B | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 |
| GLM-4.7 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 |
| ERNIE-4.5 | 1 | 2 | 2 | 2 | 1 | 1 | 1 | 2 |
| Gemma-4-31B | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 |
| gpt-oss-120b | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 |
| Mistral-Small-3.2 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 |
六类文本
中文长段(175 字符)
大语言模型(LLM)的计费单位是 token:模型先把文本切成 token,再根据 token 数量计费和限制上下文。英文单词通常被切成 1~2 个 token,而中文往往一个汉字就要 1~3 个 token——所以同一段话,在不同模型上算出来的 token 数可能相差两三倍。例如 GPT-4o、Qwen、DeepSeek 使用的分词器就完全不同。
英文段落(394 字符)
Tokenization is the first step of every language model. Before a model can read a sentence, a tokenizer splits it into subword units drawn from a fixed vocabulary. Because each vendor trains its own vocabulary on its own mix of data, the same sentence can cost 90 tokens on one model and 240 on another. That difference directly changes your bill and how much text fits into the context window.
中英混排(133 字符)
产品需求:请把「用户 feedback」按 sentiment 分成 positive / negative / neutral 三类,准确率不低于 92%。deadline 是下周五(2026-11-06),API 响应时间 P95 < 300ms。优先级:P0。
Python 代码(206 字符)
def count_tokens(text: str, model: str = "gpt-oss-120b") -> int:
enc = tiktoken.get_encoding("o200k_harmony")
return len(enc.encode(text))
for m in ["gpt-oss-120b"]:
print(m, count_tokens("你好,世界"))
表情与数字(53 字符)
今天账户 +3.14159%,我:sob:了。明天见 :rocket::rocket:!价格:¥1,299.00(含税)→ 折扣 -20%。:chart_with_upwards_trend:
古诗(33 字符)
床前明月光,疑是地上霜。举头望明月,低头思故乡。——李白《静夜思》
六类文本的 token 数
| 模型 | 中文长段 | 英文段落 | 中英混排 | Python 代码 | 表情与数字 | 古诗 |
|---|---|---|---|---|---|---|
| MiniMax-M2.5 | 87 | 80 | 54 | 68 | 37 | 24 |
| Kimi-K2.6 | 91 | 80 | 56 | 64 | 39 | 25 |
| Qwen3.5-9B | 94 | 83 | 63 | 71 | 50 | 26 |
| DeepSeek-V4-Pro | 94 | 81 | 57 | 73 | 41 | 25 |
| Hunyuan-A13B | 95 | 83 | 65 | 67 | 50 | 25 |
| GLM-4.7 | 96 | 80 | 57 | 67 | 45 | 25 |
| ERNIE-4.5 | 97 | 86 | 66 | 84 | 55 | 26 |
| Gemma-4-31B | 98 | 83 | 65 | 79 | 44 | 31 |
| gpt-oss-120b | 101 | 80 | 61 | 68 | 41 | 33 |
| Mistral-Small-3.2 | 121 | 83 | 75 | 69 | 60 | 34 |
数据来源与复现方法
所有 tokenizer 都来自 HuggingFace 模型仓库。先在仓库页面的 Files 里找分词器文件(https://huggingface.co/<repo>/tree/main),或者用 API 列出来:
 from huggingface_hub import HfApi
 print([x for x in HfApi().list_repo_files("Qwen/Qwen3.5-9B") if "token" in x])
以 Qwen3.5-9B 为例,仓库页是 https://huggingface.co/Qwen/Qwen3.5-9B/tree/main ,Files 里能直接看到 tokenizer.json 和 tokenizer_config.json。
这次用到的 10 个仓库和文件:
| 模型 | HuggingFace 仓库 | 分词器文件 | 加载方式 |
|---|---|---|---|
| MiniMax-M2.5 | MiniMaxAI/MiniMax-M2.5 | tokenizer.json | tokenizers |
| Kimi-K2.6 | moonshotai/Kimi-K2.6 | tiktoken.model + tokenization_kimi.py | transformers(trust_remote_code) |
| Qwen3.5-9B | Qwen/Qwen3.5-9B | tokenizer.json | tokenizers |
| DeepSeek-V4-Pro | deepseek-ai/DeepSeek-V4-Pro | tokenizer.json | tokenizers |
| Hunyuan-A13B | tencent/Hunyuan-A13B-Instruct | tokenizer.json | tokenizers |
| GLM-4.7 | zai-org/GLM-4.7 | tokenizer.json | tokenizers |
| ERNIE-4.5 | baidu/ERNIE-4.5-21B-A3B-Thinking | tokenizer.json | tokenizers |
| Gemma-4-31B | google/gemma-4-31B-it | tokenizer.json | tokenizers |
| gpt-oss-120b | openai/gpt-oss-120b | tokenizer.json(实际用 o200k_harmony) | tiktoken |
| Mistral-Small-3.2 | mistralai/Mistral-Small-3.2-24B-Instruct-2506 | tekken.json | mistral-common |
标准 tokenizer.json
from huggingface_hub import hf_hub_download
from tokenizers import Tokenizer
path = hf_hub_download("Qwen/Qwen3.5-9B", "tokenizer.json")
tk = Tokenizer.from_file(path)
ids = tk.encode(text, add_special_tokens=False).ids
assert tk.decode(ids) == text # 能还原才说明加载对了
hf_hub_download 只下载这一个文件到本地缓存(Windows 下默认在 C:/Users/<用户名>/.cache/huggingface),下次直接复用,不会重复下载。
Kimi-K2.6
仓库里没有 tokenizer.json,只有 tiktoken.model 和 tokenization_kimi.py,必须让 transformers 执行仓库里的代码:
 from transformers import AutoTokenizer
 tk = AutoTokenizer.from_pretrained("moonshotai/Kimi-K2.6", trust_remote_code=True)
Mistral-Small-3.2
仓库里只有 tekken.json。transformers 5 会尝试把它转成 tokenizer.json,但转换会丢中文;必须用 mistral-common:
from huggingface_hub import hf_hub_download
from mistral_common.tokens.tokenizers.tekken import Tekkenizer
repo = "mistralai/Mistral-Small-3.2-24B-Instruct-2506"
tek = Tekkenizer.from_file(hf_hub_download(repo, "tekken.json"))
ids = tek.encode(text, bos=False, eos=False)
assert tek.decode(ids) == text
gpt-oss-120b
不读仓库文件,直接用 tiktoken 的编码名:
 import tiktoken
 enc = tiktoken.get_encoding("o200k_harmony")
 len(enc.encode(text))
tiktoken 首次会从 OpenAI 的公开地址下载 BPE 文件并缓存。
闭源模型:没有本地分词器
GPT-5、Claude、Gemini 不提供可下载的分词器文件。只能用官方接口计数,结果通常包含模板和系统提示:
# Anthropic
from anthropic import Anthropic
client = Anthropic()
client.messages.count_tokens(model="<你的模型名>", messages=[{"role": "user", "content": text}])
# Google Gemini
from google import genai
client = genai.Client()
client.models.count_tokens(model="<你的模型名>", contents=text)
OpenAI 闭源模型没有独立的分词器文件,用响应里的 usage.prompt_tokens;不要拿 tiktoken 的旧编码去近似新模型。
Llama-4
meta-llama/Llama-4-Scout-17B-16E-Instruct 是 gated 仓库:先在 HuggingFace 登录,在模型页同意 Meta 协议,再给环境变量配 HF_TOKEN;否则下载直接 401。
本文数据怎么来的
按上面四种方式加载后,对同一段文本调用 encode(统一 add_special_tokens=False),统计返回的 id 数量;每个模型都做一次 decode 回原文校验。闭源与 gated 模型没有计入。